
DeepSeek introduced V4.1-Flash for long-context processing
DeepSeek released the multimodal Mixture-of-Experts (MoE) model DeepSeek-V4.1-Flash with 552 billion parameters and context support up to one million tokens. The model processes images and text, generating responses autoregressively. Weights are available on Hugging Face under the MIT license.
The Causal Encoder-Decoder (CED) architecture is a 40-layer transformer: 20 layers of causal encoder and 20 layers of decoder. During input processing, 8 billion parameters are activated per token, during generation — 16 billion. This reduces computational costs for tasks with long context.
The global key-value cache has been reduced to 890 bytes per token — about four times less than DeepSeek-V4-Flash. Compressed sparse attention CSA2, FP4 caching, and the SWA Bounded Replay method are used. The model also employs Engram memory with 196 billion parameters and speculative decoding DSpark.
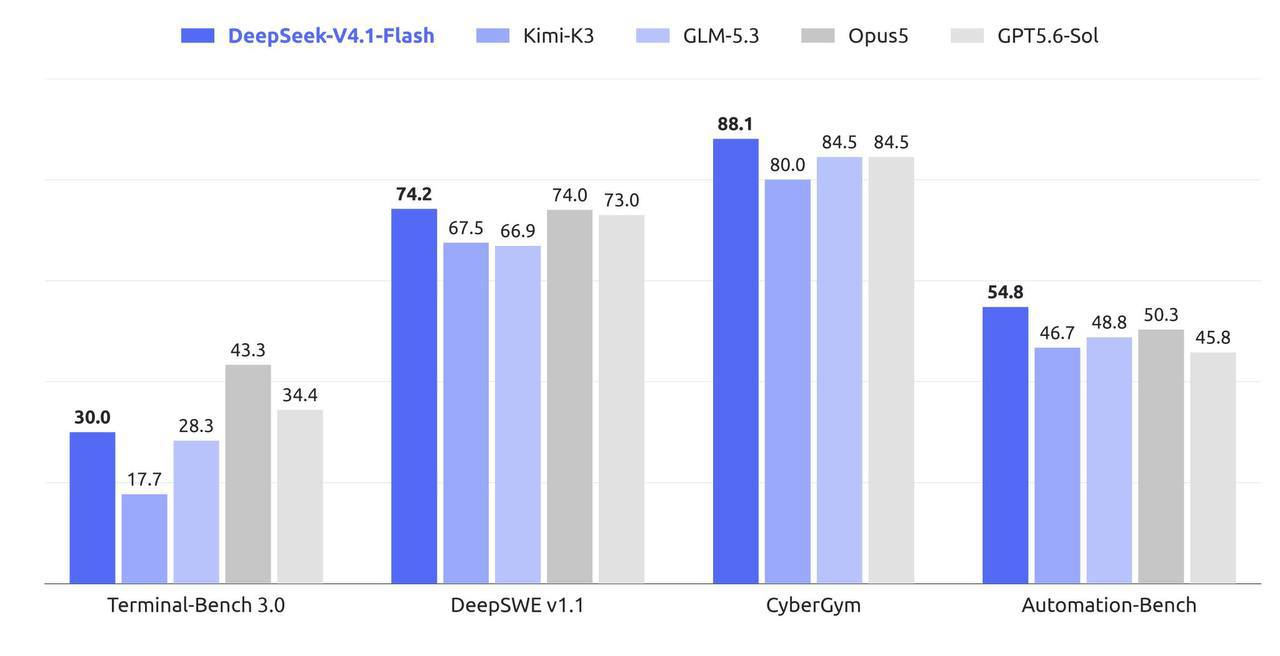
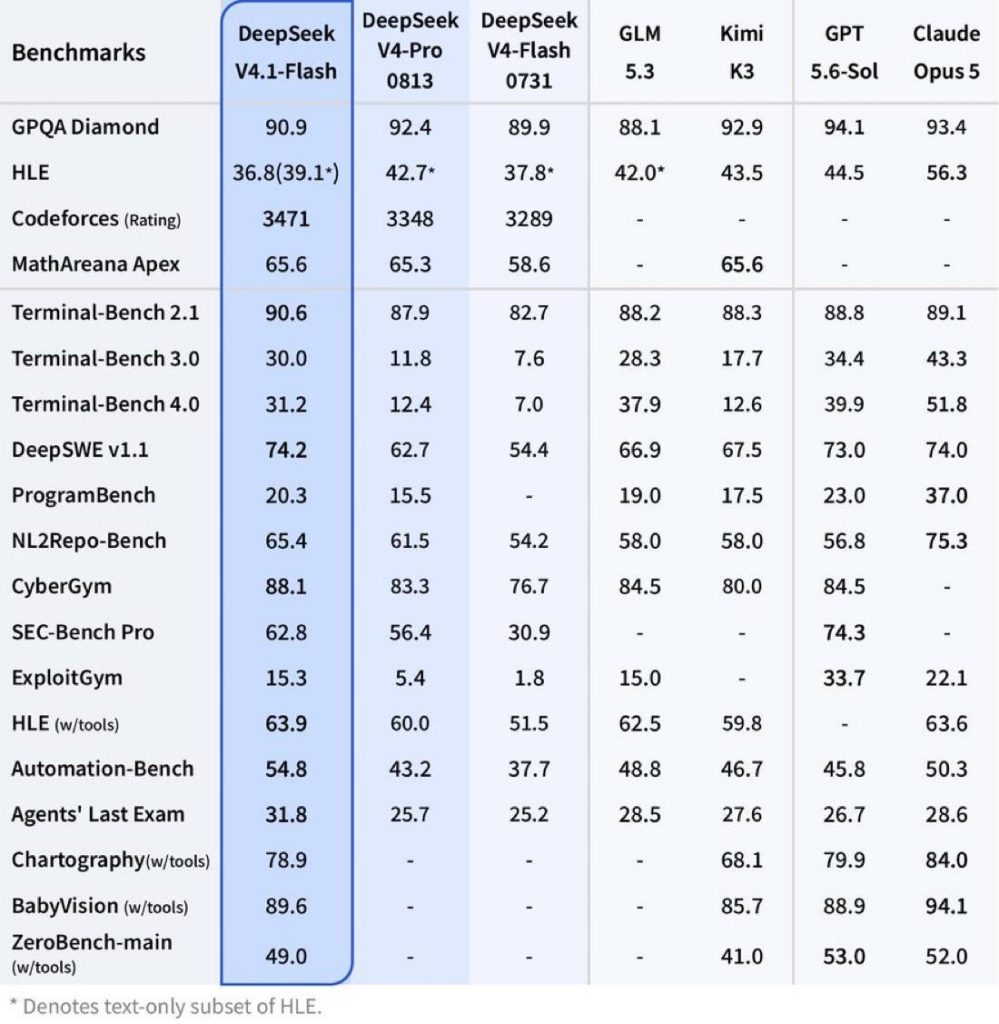
According to DeepSeek’s estimates, on the DeepSWE v1.1 benchmark the model scores 74.2 points, slightly ahead of Opus-5.0 (74.0) and GPT-5.6 Sol (73.0). In the CyberGym test, the result is 88.1 versus 84.5 for GPT-5.6 Sol. On Terminal-Bench 2.1 the model scored 90.6 points. These figures are for maximum reasoning effort (reasoning_effort=100).
In some benchmarks, such as Terminal-Bench 4.0 or ProgramBench, the new model falls behind Opus-5.0. Results may vary depending on the agent framework: for DeepSWE v1.1, values from 65.5 to 74.2 are reported in different environments.
The model supports continuously adjustable reasoning effort from 1 to 100, allowing balancing accuracy and computational costs. The deepseek-recipe library and reference implementation for prompt encoding have been released; there are guides for local deployment via vLLM, SGLang, and Transformers. Over the past month, the model has been downloaded more than 288,000 times.
Reducing activated parameters and compressing the cache can make deploying models for long context cheaper, but independent verification of the claimed indicators is still pending.
Primary source: huggingface.co ↗