
Qwen open-sources Qwen-Image-2.1: generation and editing in a single model
XORit Editorial · Sources, AI assistance and corrections
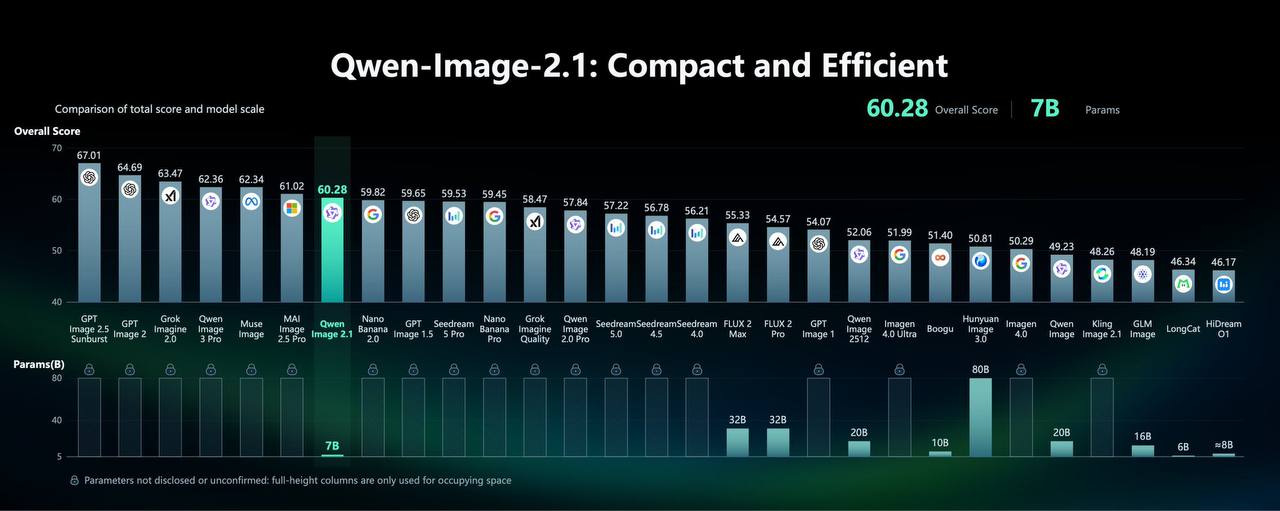
On September 20, Qwen open-sourced Qwen-Image-2.1 — a model that, within a single set of weights, can both generate images from text descriptions and edit them. The visual part weighs about 7 billion parameters, so the bet is on low compute cost rather than chasing records.
Technically, it is a single-level DiT with 32 layers: text is masked per token, images by blocks. The Qwen3-VL 8B text encoder maps instructions and conditioning images into a shared representation, and a prefix KV cache reuses them across denoising steps — which speeds up editing with multiple references.
As for the details: the model natively produces images with a transparent background (RGBA), accepts up to 10 references, and edits only the marked regions — circled, painted over, or specified by a separate mask. The model targets 2K (2048×2048 by default at 40 denoising steps), and improved typography and portrait lighting are also claimed.
Two prompt-rewriter models based on Qwen3.5-VL 9B were released separately — one for generation and one for editing.
The weights are available on HuggingFace and ModelScope. Day-one support was announced by diffusers via QwenImage21Pipeline, ComfyUI (ready-made Comfy-Org weights and workflow examples), vLLM-Omni with FP8 quantization and prefix caching, as well as SGLang and LightX2V.
The license is the Qwen Research License Agreement; among other things, it covers running on AMD Radeon GPUs via ROCm and multi-chip builds within FlagOS.
Translation editor: Салтанов А.
Source: github.com ↗